The idea and how the system works
Problem
The ERP portal at my college was ugly to begin with, and apart from a per-subject percentage it gave you no real analysis of your attendance.
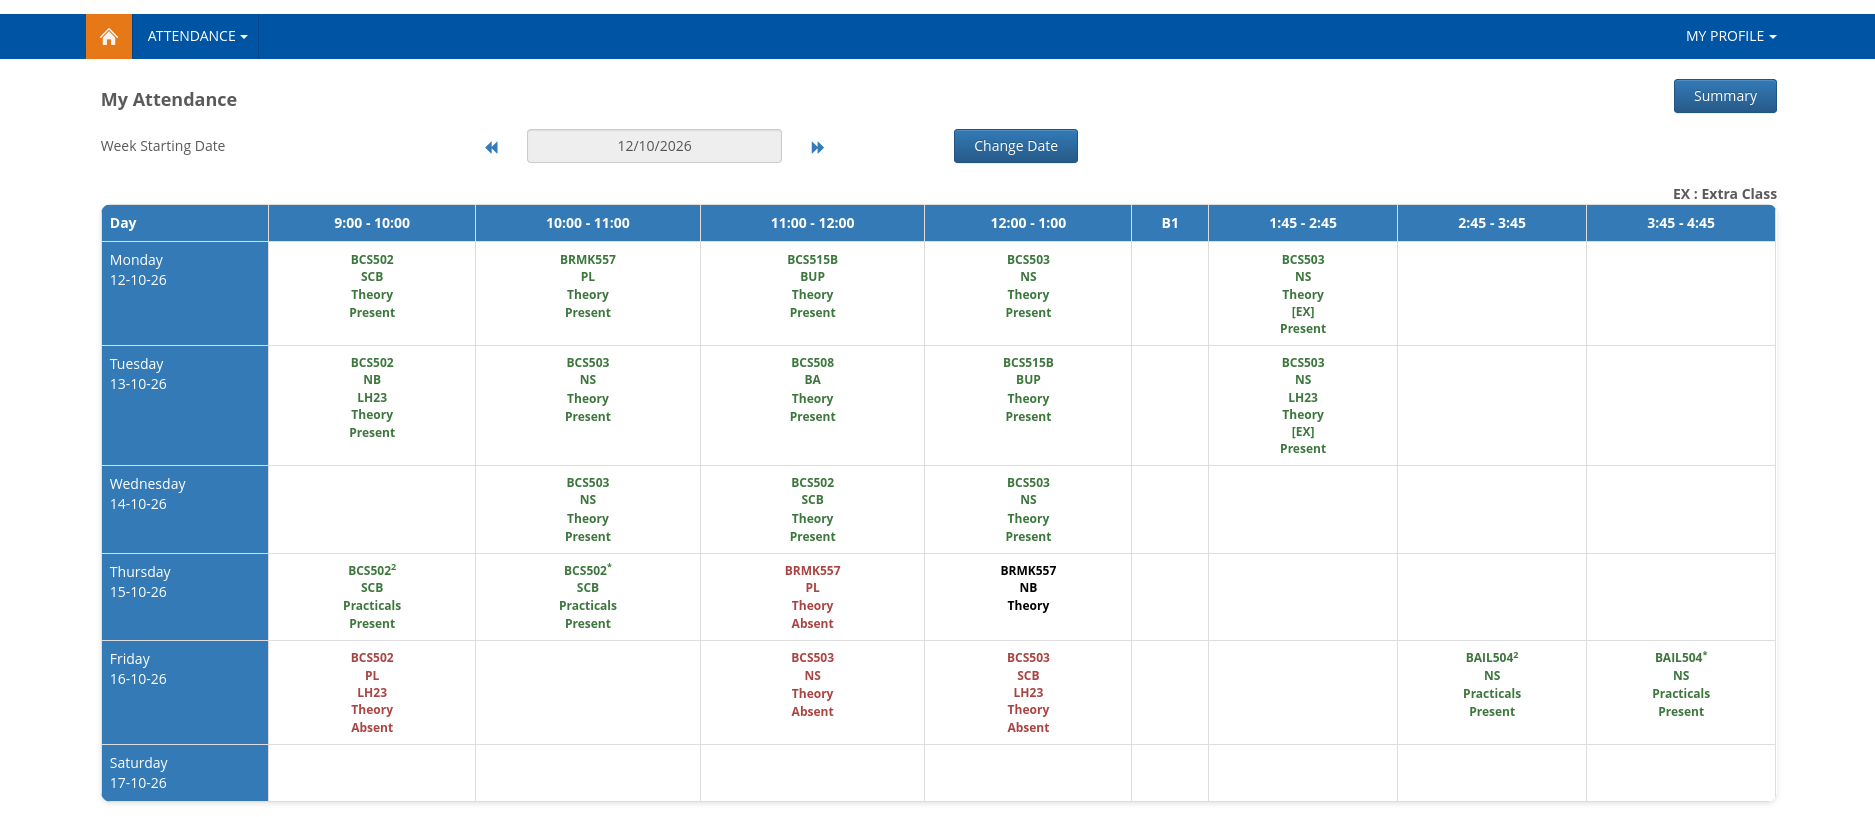
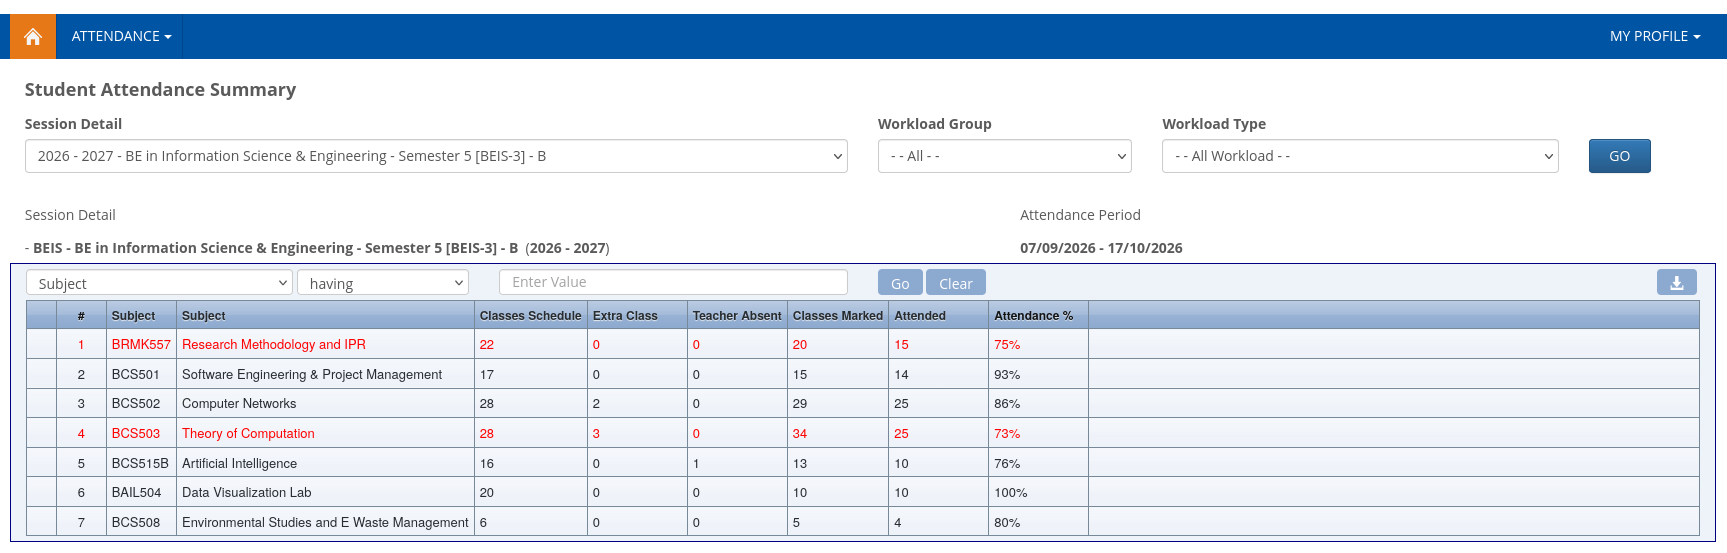
I used to screenshot every attendance page and then manually calculate my overall percentage and worse, how many classes I could miss or had to attend to hold a safe percentage. It was way too much work to keep up with every semester.
So why not automate it?
Solution
Build a system that scrapes the portal and hands back the calculations and analytics on a mobile-first web app.
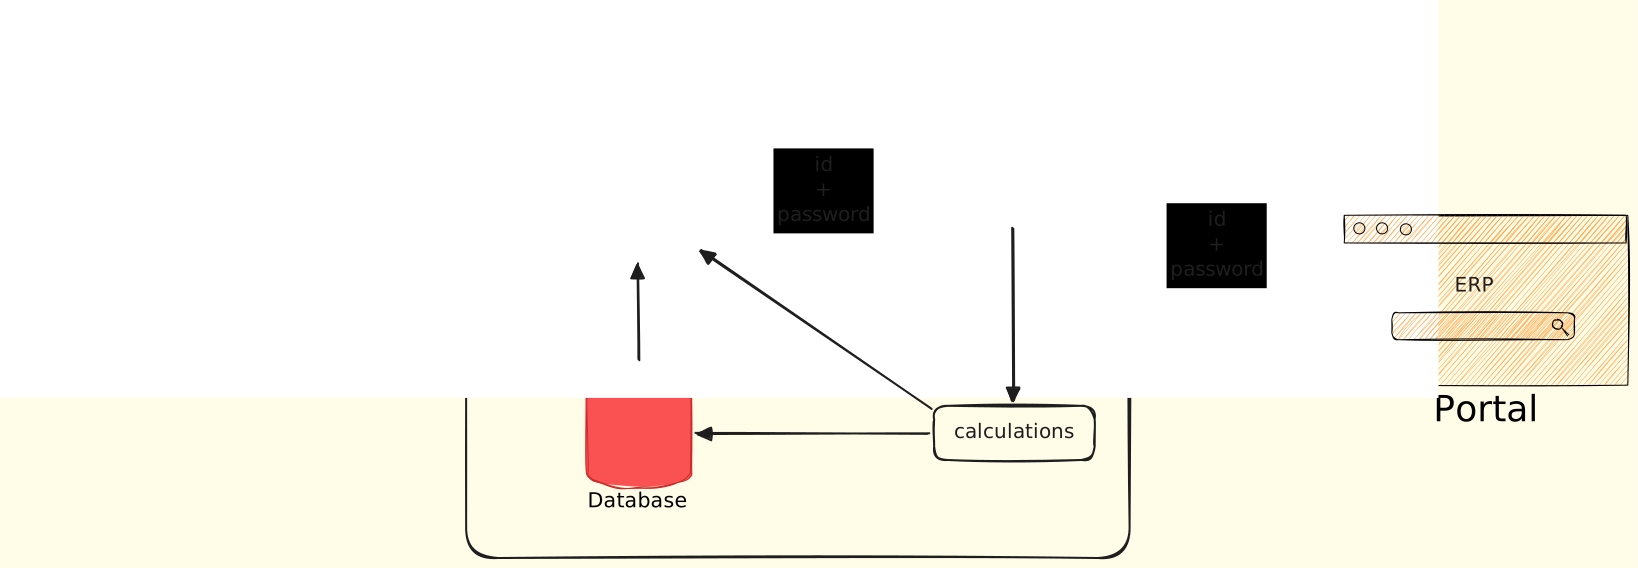
User flow
- Enter the
portal ID+password. - The credentials are sent to the backend.
- The
scraperlogs in with them and scrapes the attendance. - The scraped data is passed on for calculations and analysis.
- The results are stored in the database and forwarded to the
API gateway. - From there, the data is served back to the
web app.
The password is never stored or saved in the backend, it only exists in the memory.
What it actually shows you
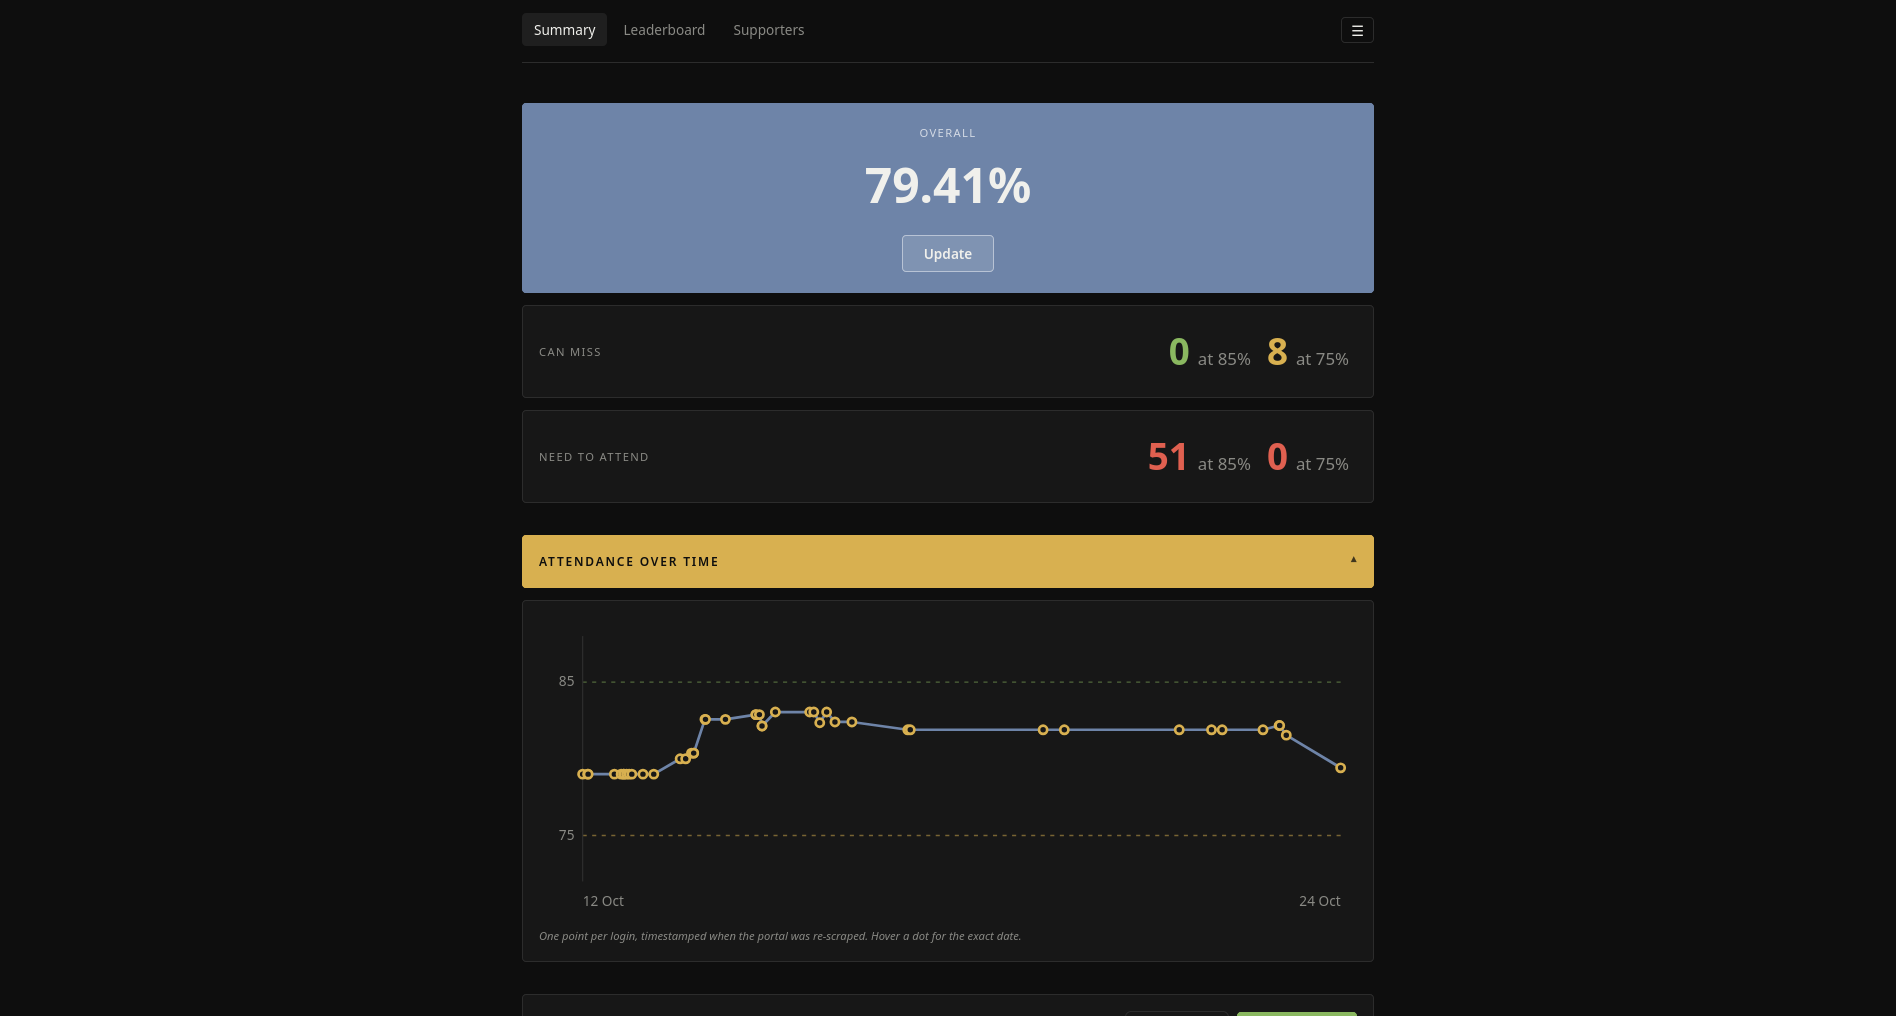
- Overall attendance at a glance green past 85%, amber 75–85%, red below.
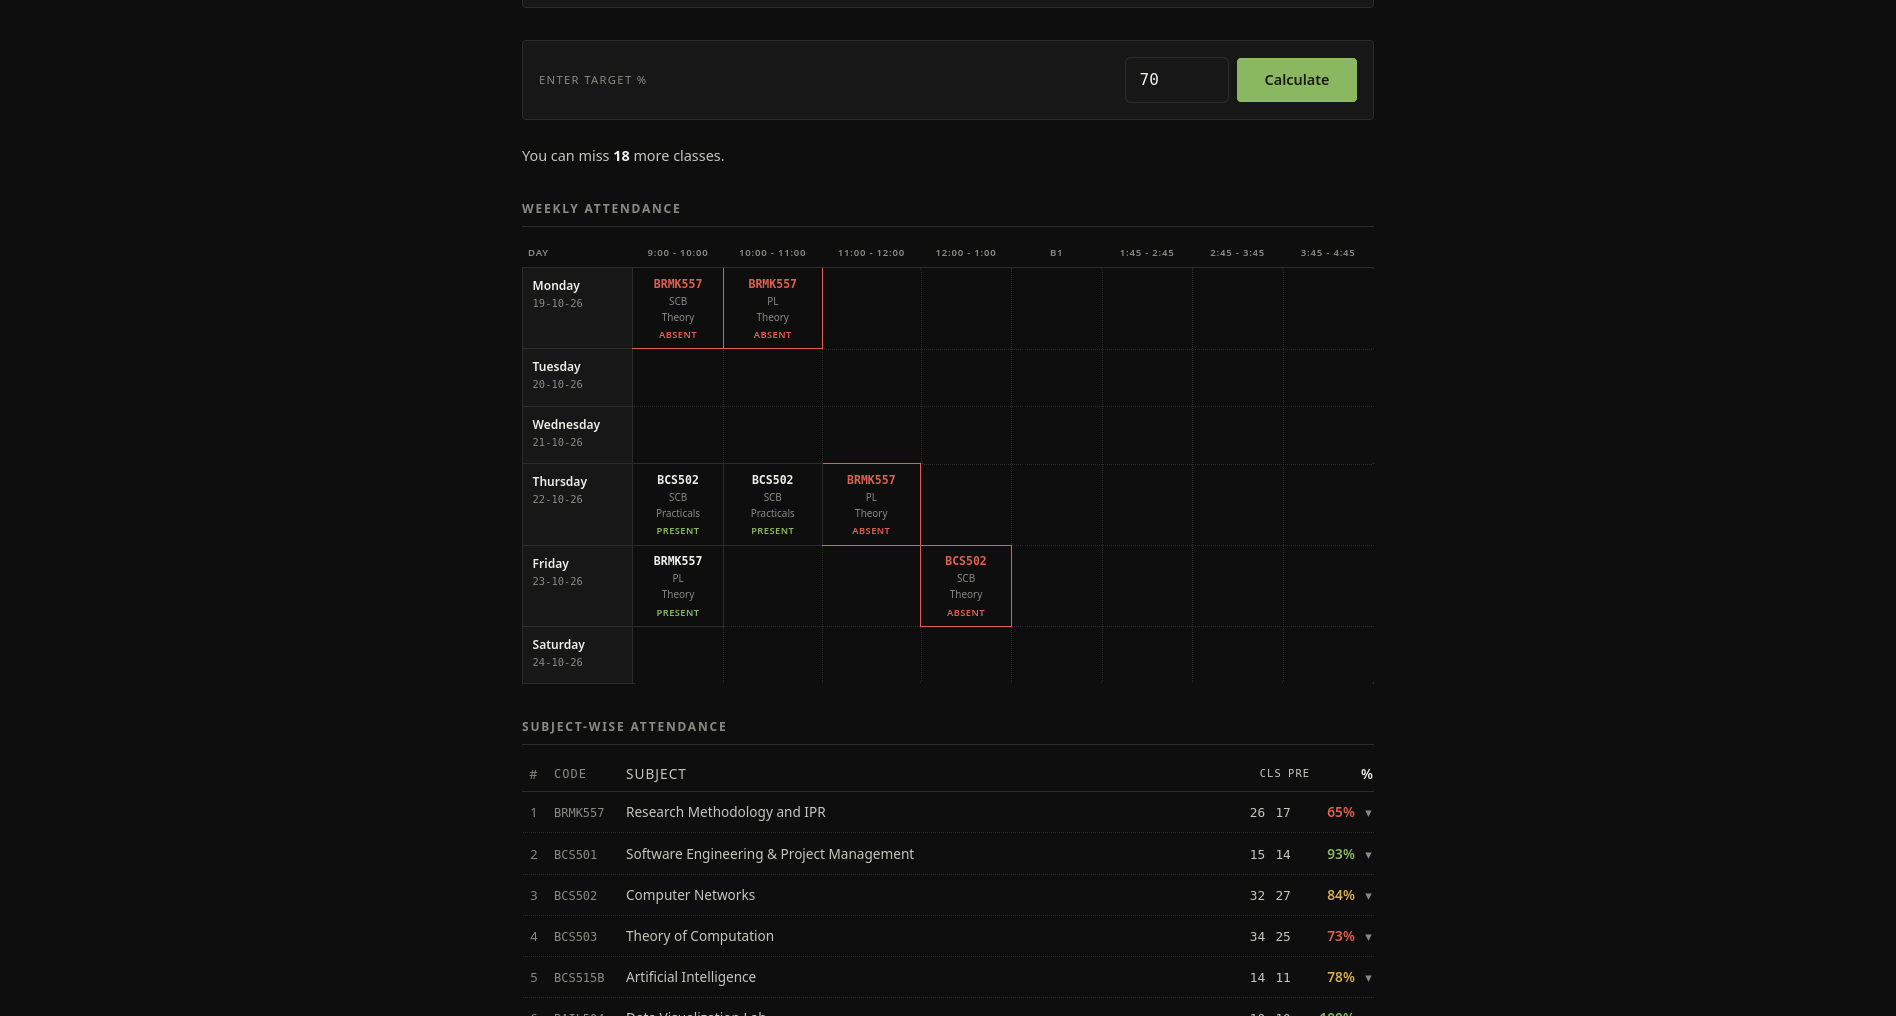
- Subject-wise breakdown in a clean table: classes held, classes attended, percentage.
- The question the portal never answers "how many classes can I miss?" at the standard 75% / 85% marks, or at any target you type in, across all subjects or for a single one (just click the row).
- Weekly timetable what's today, plus which periods you were absent.
- Attendance over time one checkpoint per login, so you watch the dip happen before the portal shows you the red.
- Leaderboard opt-in, behind a fake name, filterable by branch. Nobody ever sees your USN.
- Supporters wall the students who chipped in to keep it running.
How it works
The portal has no API it's an ASP.NET WebForms app held together with postbacks. Rather than driving a headless browser, the backend replays the exact form submissions the browser makes RSA-encrypting the password the same way the login page does using httpx, then parses the HTML with BeautifulSoup. Lightweight enough to run on a small instance and fast enough that nobody notices.
Scraping happens once per login; everything after that reads from Postgres. The portal is slow enough as it is querying it on every page view would be miserable for everyone, including the portal.
- Backend: FastAPI, SQLAlchemy, Alembic, JWT.
- Frontend: React + Vite, no UI kit and no chart library the attendance-over-time graph is ~60 lines of hand-rolled SVG, so there's nothing new to install.
- Shipping: push to main → GitHub Actions applies migrations and restarts the service; the frontend ships on Vercel. Two pipelines, one repo.
Privacy & security
- The password exists in memory for the length of one scrape, then it's gone. Never in the database, never in a log file.
- The leaderboard is opt-in and alias-based participation is a choice, and identity stays yours.
- The donation review panel is double-gated: a valid admin JWT and a separate panel credential. A stolen token alone can't approve anything.
A thing I changed my mind about
The "classes you can miss" numbers started life as database columns, recomputed and rewritten on every login. They're now computed on read one migration dropped four columns, the API's JSON shape didn't change, and the frontend never noticed. Derived data has no business being stored.
Final result: